
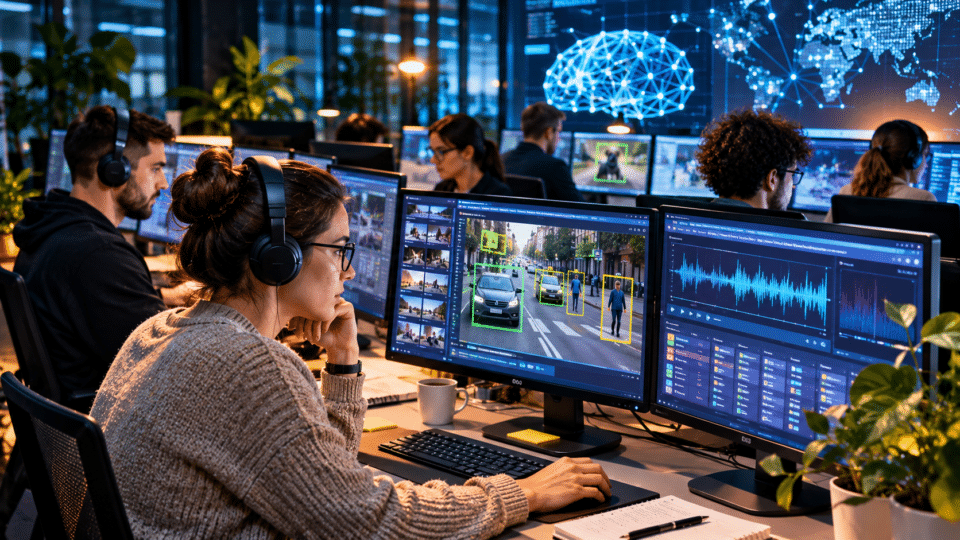
The invisible work behind artificial intelligence is carried out by people who select data, label images, compare responses, identify errors, verify information and test dangerous scenarios. Without these activities, many AI models would be less useful, less safe or harder to assess. While the user sees a conversation with a machine, behind it there may be a complex chain of human work, subcontracting and editorial decisions.
Who are these workers? What exactly do they do? How are they paid, what risks do they face and what rights might they have? InfoBuz examines the technology, the economics of digital labour and the European legal framework, separating documented facts from assumptions about companies or countries. There is no publicly verifiable figure showing exactly how many people work for all AI systems worldwide.
What invisible AI work means in practice
Some human work takes place before a model is trained, some while it is being refined, and a third part continues after launch. Not all systems use the same processes. A language model, an image-recognition system and a moderation tool can have very different workflows.
| Stage | Possible human work | What it produces |
|---|---|---|
| Data preparation | Cleaning, classification, deduplication, filtering | More consistent datasets |
| Annotation | Marking objects, audio segments, entities and relationships | Examples for learning and testing |
| Supervised fine-tuning | Writing or correcting example responses | Behaviour better aligned with the intended tasks |
| Preference evaluation | Comparing several responses | Signals for optimising behaviour |
| Safety testing | Identifying dangerous instructions and errors | Reports and test cases |
| Post-launch evaluation | Analysing failures, complaints and edge cases | Improvements and ongoing monitoring |
1. Data annotators: the people who explain what a machine sees
An annotator may draw bounding boxes around pedestrians in traffic images, mark utterances in an audio recording, identify items in a document or classify a message according to precise rules. In other projects, the task may require medical, legal or linguistic expertise. Annotation is not synonymous with simply clicking a button: instructions, ambiguities and quality control can be complex.
Consider a photograph of a pedestrian partly obscured by a car. One worker may be instructed to mark only the visible part, while another may be asked to estimate the entire silhouette. If the annotation guide does not establish the rule, results can become inconsistent. This is why serious projects use instructions, examples, audits and procedures for resolving disagreements.
2. Response evaluators: why AI also learns through comparisons
In some methods used to refine language models, people compare two or more answers to the same question. Depending on the project criteria, they may assess usefulness, compliance with instructions, accuracy or safety. The resulting data can be used to train a reward model or for other preference-optimisation methods.
The term RLHF means “reinforcement learning from human feedback”. Not all models and versions use precisely the same technique; some use direct preference optimisation, automated evaluation, feedback from other models or combinations of these. It is therefore not correct to assume that every AI response has been individually approved by a person.
Illustrative example: two answers to the same question
A user asks how to check a suspicious news story. The first answer recommends relying on the number of shares. The second calls for checking the primary source, the date, the context and independent confirmations. An evaluator may prefer the second answer using explicit criteria. This is an example constructed for explanatory purposes, not a real conversation from any company’s internal dataset.
3. Red teaming: those trying to make a system fail
Adversarial testing, often called “red teaming”, involves exploring the system’s limits: false information, contradictory instructions, security vulnerabilities, biases or dangerous responses. Tests may be carried out by employees, contractors, independent researchers and specialist teams, depending on the organisation.
An evaluator should not be confused with a cybersecurity specialist, and a “red teamer” is not automatically a hacker. These roles may involve very different levels of expertise and access. The NIST AI Risk Management Framework provides a framework for managing AI risks, without claiming that a single round of testing can eliminate every risk.
4. Content moderators and exposure to difficult material
Some data-preparation, filtering and evaluation workflows may involve reviewing disturbing material: violence, abuse, threats or sexually explicit content. Not all AI workers are exposed to such material, but for those involved in these tasks, protective measures matter: selecting content, limiting exposure, breaks, psychological support, the option to refuse tasks and reporting procedures.
It is important not to treat all companies, contracts or countries as identical. Conditions can vary substantially even between projects run by the same provider. A sound investigation requires documents, verifiable testimony, responses from the companies concerned and a clear distinction between individual cases and broader trends.
5. Who actually hires the people who train AI?
The chain may include the model developer, a data-services provider, regional subcontractors, microtasking platforms and independent workers. Someone may work on evaluating a system’s responses without being directly employed by the company marketing the application.
| Working arrangement | How it may work | Transparency question raised |
|---|---|---|
| Direct employee | An employment contract with a company | What are the tasks, pay and protections? |
| Contractor through a provider | The provider manages teams for a client | Who is responsible for labour standards? |
| Freelancer | Tasks contracted individually | How is payment set, and who resolves disputes? |
| Microtasking platform | Many small tasks allocated digitally | Is waiting and checking time paid? |
| Domain expert | Specialist evaluation in medicine, law, programming and other fields | How are competence and confidentiality verified? |
The International Labour Organization has documented the role of digital platforms in changing work, as well as differences in social protection, remuneration and bargaining power. These findings concern the digital platform economy in general and cannot automatically be turned into a percentage for all AI evaluators. ILO — World Employment and Social Outlook 2021: Digital Labour Platforms.
How AI annotators and evaluators are paid
Pay may be set by the hour, by task, by project or through contracts with negotiated rates. An offer promising a certain amount “per hour” may conceal unpaid time spent qualifying, reading instructions, waiting for tasks or correcting rejected work. That is why a more useful indicator than the advertised rate is effective earnings in relation to all working time.
Calculation example: nominal pay versus effective pay
A purely illustrative scenario: a worker receives 40 Romanian lei for 20 completed tasks. If these take two hours, the apparent rate is 20 lei per hour. If the worker also spends 45 minutes on instructions and waiting, plus 15 minutes on corrections, the effective gross income is 40 lei divided by 3 hours = 13.33 lei per hour, before taxes and costs. This is not a statistical average and does not describe a particular platform.
Other questions are equally important: who decides that a task is wrong, can a rejection be appealed, are quality criteria transparent, and can the worker obtain data on their own performance?
What research says about working conditions on platforms
The Fairwork programme assesses platform working conditions against principles including fair pay, fair conditions, fair contracts, fair management and representation. Its reports on cloudwork show why both pay and mechanisms for appeal and protection need to be examined. Fairwork scores are not a universal ranking of all AI companies and must be read for the year and platforms actually assessed. Fairwork — Cloudwork Ratings.
Initiatives such as Partnership on AI — Responsible Sourcing discuss the responsibility of organisations that purchase data-enrichment and labelling services. Industry recommendations do not replace labour law, but they can inform procurement, supplier audits and protection for people carrying out the tasks.
Global work, but no complete global statistic
Digital tasks can be distributed across countries and time zones, sometimes without the end user knowing where they were completed. This can create income opportunities, but also major differences in bargaining power and protection. It is tempting to publish an impressive figure for “AI’s invisible workers”; without a methodology that distinguishes employees, contractors, microtasking and occasional evaluations, such a number would be misleading.
The ILO report on generative AI’s impact on work analyses occupations’ exposure to automation and transformation; it does not provide a census of people who label data. These are two distinct questions. ILO — Generative AI and Jobs: A Global Analysis.
AI quality also depends on the quality of human work
A set of incorrect labels can affect a model’s evaluation. An ambiguous instruction can produce systematic disagreements. A group of evaluators that is too homogeneous may fail to capture certain cultural or linguistic variations. If payment rewards speed over attention, the data may become noisier.
- Clear annotation guides and examples for ambiguous cases.
- Independently checked samples with explicit quality criteria.
- Evaluators familiar with the language and cultural context of the data.
- Procedures for adjudicating disagreements, rather than simply removing them.
- Protection of personal data and controlled access to sensitive material.
- Pay that does not penalise the time required for quality.
- Monitoring errors after the model is launched.
The Romanian language: why local evaluators matter
A model may produce grammatically correct sentences yet misinterpret regional expressions, irony, administrative conventions or cultural contexts. Evaluation in Romanian often requires proficient speakers and examples relevant to Romania. Machine translation cannot always substitute for legal, medical or cultural checks performed by a specialist.
This does not demonstrate that every AI developer uses teams of Romanian evaluators, nor does it make it possible to identify its internal contracts. It explains the methodological need for localised evaluation; it is not a claim about a particular provider.
The AI Act: what the European Union requires — and what it does not
The EU’s Artificial Intelligence Regulation, Regulation (EU) 2024/1689 — the AI Act, includes obligations on data governance, documentation, risk management, human oversight and evaluation, depending on the category of system and the operator’s role. Its implementation timetable is phased and has been subject to proposed adjustments, so obligations should be checked in the relevant version and at the relevant date.
Article 14 concerns human oversight of high-risk AI systems. This does not mean a person manually approves every answer from every chatbot. Article 10 concerns data governance and quality practices for high-risk systems in the circumstances provided for. The regulation does not set a single rate for annotators and does not automatically turn all contractors into employees.
For a separate overview of the implementation stages, see InfoBuz’s analysis on the AI Act in 2026–2028. Transparency rules for certain types of AI content are covered in InfoBuz’s guide to labelling AI content.
The Platform Work Directive: what it could change
Directive (EU) 2024/2831 seeks to improve working conditions in platform work, including the determination of employment status and algorithmic management. Member states have until 2026 to transpose it, while its concrete effects depend on national law and the worker’s legal situation.
Not everyone working for an AI data provider automatically falls within the directive’s scope. A direct employee of a technology company, an independent consultant and a worker receiving tasks through a platform may be subject to different arrangements. Each case requires an examination of the contract, how tasks are allocated and the applicable law.
Confidentiality: what data evaluators may see
Evaluation may involve text, images, sounds or conversations collected for specific purposes. Data protection requires limited access, retention rules, security and an appropriate legal basis where applicable. It should not be assumed that every private conversation with an AI assistant is read by a human worker; practices differ between products, settings and policies.
For companies, relevant transparency includes the categories of data reaching contractors, anonymisation measures, retention periods, supplier agreements and access controls. For users, privacy policies and product settings are the starting point.
When human feedback can introduce bias
Evaluators are not neutral instruments. They interpret rules, have cultural experiences and can make mistakes. This does not mean human evaluation is useless; it means it must be designed and checked. Multiple evaluators may hold different views on subjective questions; sometimes disagreement is useful information rather than a flaw to be concealed.
UNESCO’s recommendation on the ethics of artificial intelligence emphasises human rights, fairness, diversity and accountability. These principles help explain why AI evaluation is not merely a technical issue. UNESCO — Recommendation on the Ethics of Artificial Intelligence.
Can AI replace its own evaluators?
Models can be used to generate preliminary labels, compare answers or identify examples worth reviewing. This may reduce some repetitive tasks and create others: checking automated errors, assessing sensitive domains and auditing the process. An automated evaluator may reproduce its own biases or mistakes, which is why independent checking remains important.
Neither the claim that “AI will eliminate all annotators” nor the claim that “their numbers will inevitably grow” can be supported without data on changes in tasks, productivity, costs and demand. The impact may differ between basic annotation and specialist evaluation.
What responsible procurement of data services looks like
| Question for the developer or provider | Evidence that would matter |
|---|---|
| Who carries out the tasks? | Contract structure and a list of subcontractor categories |
| How is pay calculated? | Rates, actual time and rules for rejected tasks |
| Is psychological protection available? | Procedures for difficult content and access to support |
| How can decisions be challenged? | An accessible, documented appeals mechanism |
| How is quality checked? | Audits, samples, instructions and adjudication |
| What data are exposed? | Privacy policies, access controls and retention |
| Are relevant languages represented? | A multilingual evaluation plan and verified skills |
How InfoBuz could investigate Romania’s AI labour market
A serious local investigation would begin with recruitment advertisements, publicly available contracts, commercial registers, voluntary interviews and requests for information to the competent institutions. Each testimony would need to be corroborated by documents, and interviewees protected where there is an occupational risk. This article does not describe a Romanian company as exploitative without evidence.
- Collecting offers for “AI trainer”, “data annotator”, “AI evaluator” and “content reviewer”, with the date and country recorded.
- Separating expert roles from repetitive microtasking.
- Calculating effective earnings only from verifiable, comparable data.
- Interviewing workers who agree to take part, while checking documents and protecting identities.
- Seeking responses from the platforms and subcontractors concerned.
- Checking rules on contracts, taxation and data protection.
- Publishing the methodology, limitations and right of reply.
What someone seeking work as an AI evaluator should know
A legitimate offer may require language tests, technical knowledge or evaluation assessments. Before accepting, a candidate should verify the company’s identity, contractual conditions, jurisdiction, payment arrangements and confidentiality rules. Be wary of requests for registration fees, money transfers for “activation”, identity documents sent through insecure channels and promises of guaranteed income.
For work involving sensitive material, it is reasonable to ask whether tasks can be refused, how breaks are managed and what support is available. Where the work is independent, local tax obligations must also be considered; payment through a platform should not be assumed to remove those obligations.
Frequently asked questions about invisible AI work
Who trains ChatGPT, Gemini or Claude?
Models are developed by technical teams and may use data and feedback from multiple sources, including human evaluation, depending on the product and method. There is no complete, comparable public list of every contractor and evaluator for each version.
Do all AI evaluators work for low pay?
No. Rates and contracts vary by skills, region, task type and employer. There is both repetitive work and specialist evaluation; generalisations about all workers are unjustified.
What is RLHF?
A family of techniques through which human feedback helps refine a model’s behaviour. It does not mean every response is written or checked manually.
What is the difference between annotation and moderation?
Annotation adds labels or structures to data; moderation assesses content against rules on acceptance, restriction or safety. Some projects may combine these activities.
Can someone in Romania work in this field?
Yes. Some types of roles can be performed remotely, but the availability of vacancies and the specific conditions must be checked at the time of application. We do not recommend a particular platform without verifying it.
Does the AI Act require human approval of every answer?
No. Human-oversight requirements are specific to certain systems and situations, particularly high-risk ones. They are not a universal rule for all AI responses.
Is there an official worldwide number of AI workers?
We have not identified a complete official census using uniform definitions for every type of annotator, evaluator, moderator and contractor involved in AI.
Conclusion: artificial intelligence is also an industry of human labour
The invisible work behind artificial intelligence explains why an apparently automated product may depend on people at essential stages: preparing data, assessing quality, safety and monitoring. A mature discussion of AI cannot measure only model performance or server costs. It must also include the quality of work, subcontractor accountability, data protection and the right to fair conditions.
To understand the technical side of models, InfoBuz has separately published a comparative guide to AI engine families. This article deliberately focuses on the people and processes that usually remain outside the interface.
Official sources, research and editorial transparency
- International Labour Organization — World Employment and Social Outlook 2021: conditions and structure of work on digital platforms.
- International Labour Organization — Generative AI and Jobs: transformation of occupations; not a census of AI evaluators.
- Regulation (EU) 2024/1689 — the AI Act: data governance, risks and human oversight within its scope.
- Directive (EU) 2024/2831 on platform work: employment status and algorithmic management.
- NIST — AI Risk Management Framework: AI risk management and assessment.
- UNESCO — Recommendation on the Ethics of AI: principles of rights, fairness and accountability.
- Partnership on AI — Responsible Sourcing: recommendations for responsible sourcing of data services.
- Fairwork — Cloudwork Ratings: independent assessments of working conditions on platforms.
Editorial note, 17 November 2026: the evaluation examples and remuneration calculation are illustrative. This article does not claim that all AI providers use the same methods, does not attribute abuses to companies without documentation, and does not present estimates of the global number of workers as official statistics. The image is AI-generated and does not depict real employees.








Discuția cititorilor
Ai o opinie sau o întrebare despre acest articol? Spune-ne ce crezi.
Fii primul care deschide discuția.
Te rugăm să păstrezi un limbaj civilizat și să discuți la subiect. Comentariile spam sunt filtrate automat.